
Admin guide · Platform
Guardrails
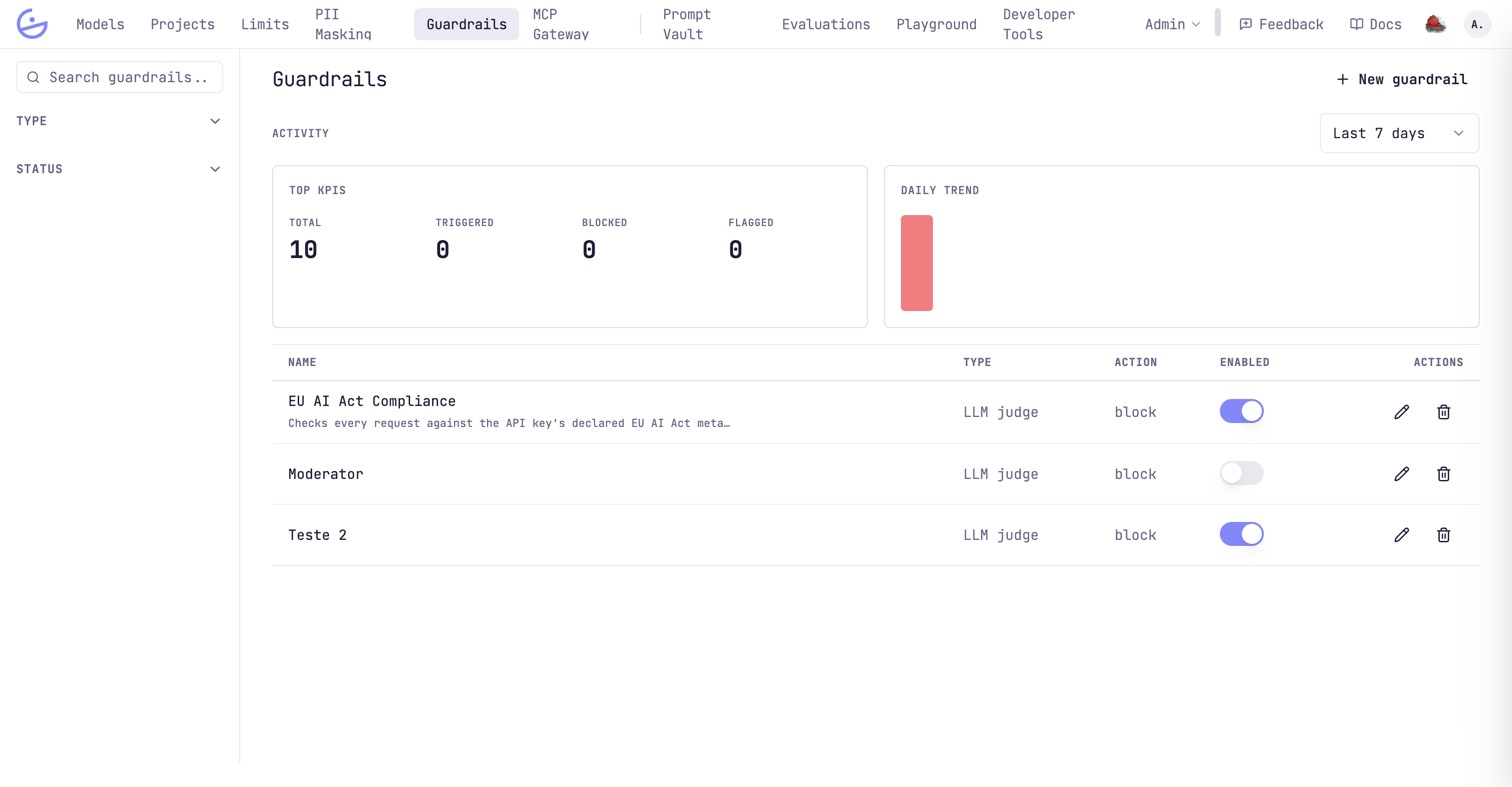
Policy rules evaluated on every request before it reaches the model. All guardrails assigned to a key must pass for the call to continue. Manage them under Guardrails.
Rules & activity
The activity strip counts triggered / blocked / flagged hits over the selected window; each rule has an Enabled toggle.
Configuring a rule
A rule's behavior is defined by three things.
| Field | Type | Description |
|---|---|---|
| Type | denylist · llm_judge | A denylist matches terms/patterns; an llm_judge asks a model to rule on the request. The type is fixed after creation. |
| Action on match | block · flag | block rejects the request; flag lets it through but records the hit. |
| Judge model & prompt | llm_judge only | The judge model and a judge prompt pulled straight from the Prompt Vault (optionally pinned to a version/tag), plus a timeout and max-input-chars. |
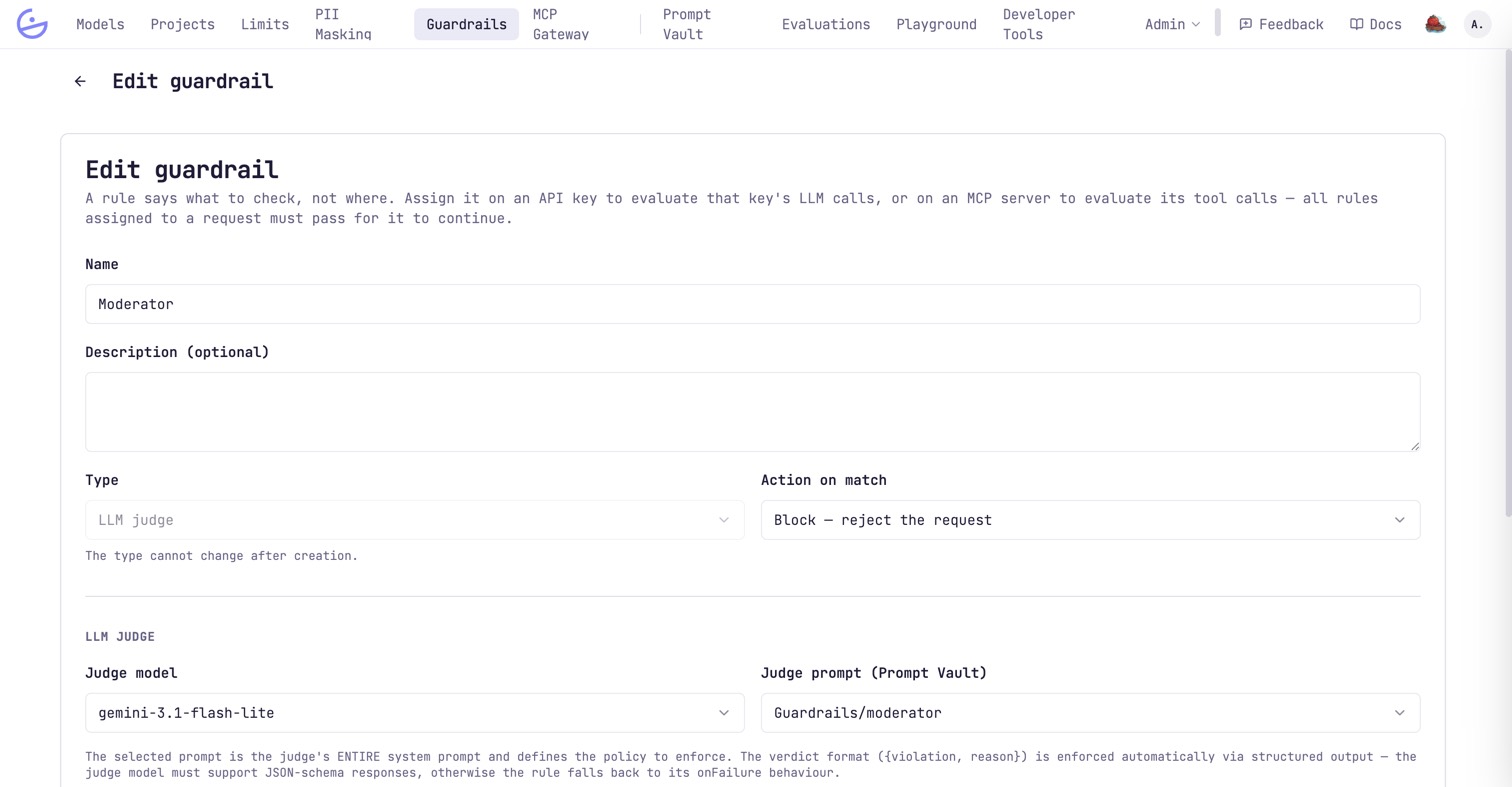
tip · A rule says what to check, not where
warning · On MCP servers the rule runs twice
EU AI Act enforcement
A separate, per-key policy that scores the prompt's EU AI Act risk level and blocks or flags high-risk or prohibited prompts.
It complements guardrails: guardrails encode your policy, while this compares live traffic against the risk level the key declared for itself. Enable it on the API-key form; the classifier behind it, and the reporting, live under EU AI Act.